import torch
from torch import nn
import torch.nn.functional as F
import transformers
from transformers import AutoTokenizer,AutoConfig,AutoModel
import numpy as np
import pandas as pd
import matplotlib.pyplot as plt
import matplotlib as mpl

summary

  • 双层MLP
  • 2个细节
    • h==>4h==>h
      • 768==>3072==>768
    • 模型的capacity和memorization(world knowledge)
    • Layer Normalization&skip connections
      • LN在整个模型拓扑结构中的位置

review multihead attention

model_ckpt = 'bert-base-uncased'
model = AutoModel.from_pretrained(model_ckpt)
print(model)
print(model.embeddings)
print(model.encoder)

print(model.encoder.layer[0])
tokenizer = AutoTokenizer.from_pretrained(model_ckpt)
config = AutoConfig.from_pretrained(model_ckpt)
config
# batch_size,seq_len,hidden_size,(b,s,h)
# 经过W_q,W_k,W_v的project之后得到query,key,value
def scaled_dot_product_attention(query,key,value):
	# hidden_size
	dim_k = key.size(-1)
	# batch_size,seq_len,seq_len
	attn_scores = torch.bmm(query,key.transpose(1,2))/np.sqrt(dim_k)
	attn_weights = F.softmax(attn_scores,dim=1)
	return torch.bmm(attn_weights,value)
class AttentionHead(nn.Module):
	def __init__(self,embed_dim,head_size):
		super().__init__()
		# learnable parameters
		self.Wq = nn.Linear(embed_dim,head_dim)
		self.Wk = nn.Linear(embed_dim,head_dim)
		self.Wv = nn.Linear(embed_dim,head_dim)
	def forward(self,hidden_size):
		# project
		q = self.Wq(hidden_states)
		# project
		k = self.Wk(hidden_states)
		# project
		v = self.Wv(hidden_states)
		attn_outputs = scaled_dot_product_attention(q,k,v)
		return attn_outputs
class MultiHeadAttention(nn.Module):
	def __init__(self,config):
		super().__init__()
		embed_dim = config.hidden_size
		num_heads = config.num_attention_heads
		# 768/12 == 64
		head_dim = embed_dim//num_heads
		self.hands = nn.ModuleList([
			AttentionHead(embed_dim,head_dim) for _ in range(num_heads)
		])
		# 768==>768
		self.output_layer = nn.Linear(embed_dim,embed_dim)
	def forward(self,hidden_state):
		print(f'input hidden_state:{hidden_state.shape}')
		print(f'head(hidden_state):{self.heads[11](hidden_state).shape}')
		x = torch.cat([head(hidden_state) for head in self.heads],dim=-1)
		print(f'cat heads:{x.shape}')
		x = self.output_layer(x)
		return x
mha = MultoHeadAttention(config)
# input
# config.vocab_size:30522
# config.hidden_size:768=64*12
# lookup-table,learnable
token_embedding = nn.Embedding(config.vocab_size,config.hidden_size)
# token_embedding
sample_text = 'time files like an arrow'
model_input = tokenizer(sample_text,return_tensors='pt',add_special_tokens=False)
# forward of embeddings module
input_embeddings = token_embedding(model_inputs['input_ids'])
# batch_size,seq_len,seq_len
input_embeddings.shape
attn_output = mha(input_embeddings)

FFN

  • ReLU:x1x_1
  • GELU:xϕ(x)x\phi(x)
  • ϕ(x)=1+Erf(x2)2\phi(x)=\frac{1+Erf(\frac{x}{\sqrt{2}})}{2}
x = np.arange(-5,5,0.01)
plt.plot(x,nn.ReLU()(torch.from_numpy(x)))
plt.plot(x,nn.LeakyReLU(negetive_slope=0.1)(torch.from_numpy(x)))
plt.plot(x,nn.GELU()(torch.from_numpy(x))
plt.legend(['relu','lrelu','gelu'])
class FeedForward(nn.Module):
	def __init__(self,config):
		super().__init()
		# config.intermediate_size:4*h == 4*768 == 3072
		# (intermediate)
		self.fc1 = nn.Linear(config.hidden_size,config.intermediate_size)
		# (output)
		self.fc2 = nn.Linear(config.intermediate_size,config.hidden_size)
		self.gelu = nn.GELU()
		self.dropout = nn.Dropout(config.hidden_dropout_prob)
	def forward(self,x):
		#b,s,h ==> b,s,4h
		x = self.fc1(x)
		x = self.gelu(x)
		#b,s,4h ==> b,s,h
		x = self.fc2(x)
		x = self.dropout(x)
		return x
ffn = FeedForward(config)
ffn(attn_attention).size()

layer norm&&skip connection

  • layer norm(config,“layer_norm_eps”:1e-12,)
    • zero mean & one variance
    • 与batch norm相对,是样本层面
    • 对于nlp问题,一般是每一个token对应的embedding(也就是768维的hidden state进行0均值1标准差的归一化)
  • 在transformers中主要是两处用到了layer norm
    • embedding
      • 对于最终的token_embedding
    • 构建bert layer(或者叫做transformer encoder layer)

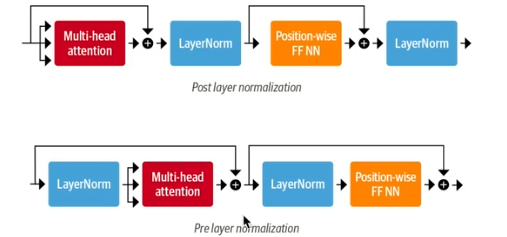
layer norm在bert layer(TransformerEncoder)中的位置

  • Post Layer Normalization(huggingface默认的实现)
  • Pre layer normalization
  • post/pre 针对的是multiheadattn
Pasted image 20261002121128.png

Encodern Layer

class TransformerEncoderLayer(nn.Module):
	def __init__(self,config):
		super().__init__()
		# 768,embedding 级别进行0均值1标准差的归一化处理
		self.ln1 = nn.LayerNorm(config.hidden_size)
		# 768,embedding 级别进行0均值1标准差的归一化处理
		self.ln2 = nn.LayerNorm(confug.hidden_size)
		self.attn = MultiHeadAttention(config)
		self.ffn = FeedForward(config)
		
	def forward(self,x):
		# x from embedding (b,s,h)
		x = x+self.attn(self.ln1(x))
		x = x+self.attn(self.ln2(x))
		# (b,s,h)
		return x
encoder_layer = TransformerEncoderLayer(config)
encoder_layer(input_embeddings).shape