basics
- 为什么要学习KD
- 必要:
- 模型结构(分支)和损失函数的设计,值得借鉴
- openai GPT一骑绝尘的时代,GPT4就是老师
- Teacher-Student paradigm
- 在训练中将teacher的知识蒸馏/transfer到student model中:
- 对于student model而言,就是Mimic(模仿)的过程
- teacher:larger,slower,better-performing
- student:smaller,faster,cheaper and lighter
- 2006年提出之后,在ensemble models(集成模型)的语境下提出来的
- 本节的重点是知识蒸馏的模型架构(loss Function)及Pipeline
理论初步
- 理论方向:
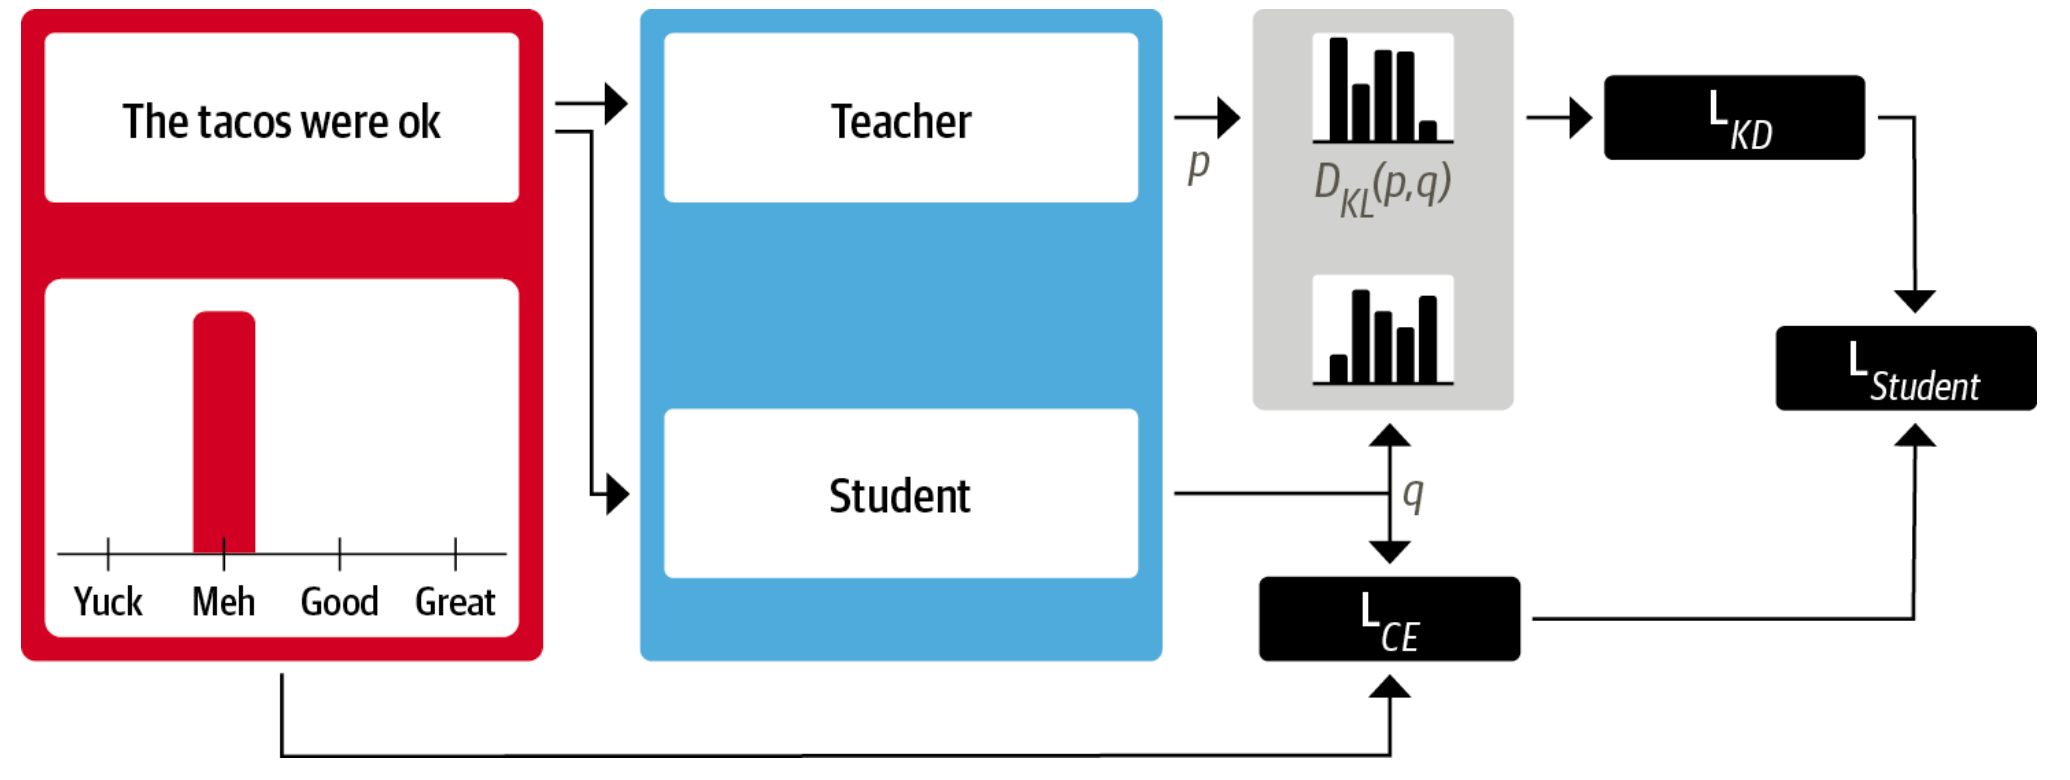
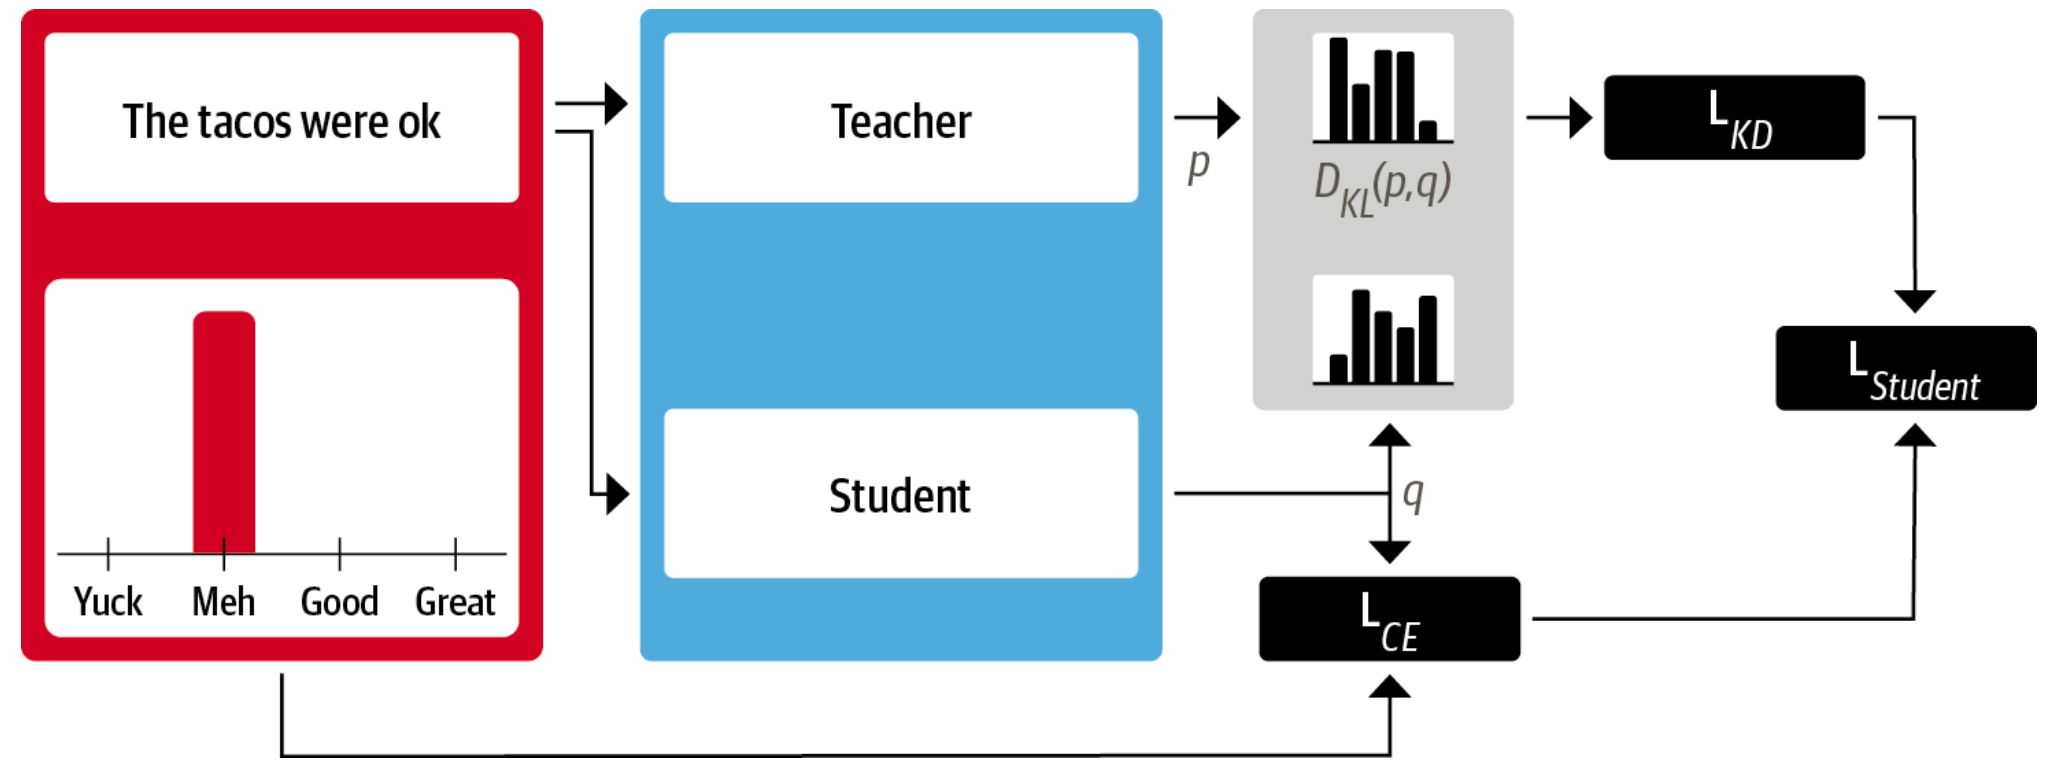
- Student model学的不是一个single value(one-hot representation),而是teacher model预测的概率的分布(dense feature representation)
- 关于多分类问题的输出:
- ground truth:hard target,one-hot encoding
- Teacher predict output:softmax(T=1)
- 假如对于一个有监督的分类问题,对于样本x
- 对于Teacher model,其output(logits)为z(x)=[z1(x),z2(x),⋯,zN(x)]
- 将其进一步通过softmax(with temperature)转化为概率化的输出:
pi(x)=∑jexp(Tzj(x))exp(Tzi(x))
- 对于student model,其预测的概率分布为qi(x)
- 此时使用KL-divergence(KL-散度)来度量2个概率分布的距离
DKL(p,q)=∑ipi(x)logqi(x)pi(x) LKD=T2DKL
- 通过KL散度,也度量了当Student model(用qi(x))来逼近/近似 Teacher model(用pi(x))的信息损失;
Lstudent=αLCE+(1−α)LKD=αLCE+(1−α)T2DKL
模型结构
kd on pretraining
- BERT开启了一个范式:pretraining+downstream tasks
- 同样的对pretraining model(比如BERT)进行distil得到DistilBert
- L(cos)=1−cos(hs,hi)不只是对其输出,还对齐(align)direction of hidden state vectors (representation space)
Ldistil−bert=αLmlm+βLKD+γLcos=αLmlm+βLKD+γ(1−cos(hs,ht))
from transformer import AutoModel,AutoTokenizer
import os
os.environ['HTTP_PROXY']='http://127.0.0.1:7890'
os.environ['HTTPS_PROXY']='https://127.0.0.1:7890‘
model = AutoModel.from_pretrained('bert-base-uncased')
kd_model = AutoModel.from_pretrained('distilebert-base-uncased')
model
def model_size(model):
	return sum(para.num() for para in model.parameters())
print(model_size(model))
print(model_size(kd_model))
print(model_size(model)/model_size(kd_model))
