
from IPython.display import Imageimport math
import numpy
import torch
import torch.nn as nn
import torch.nn.functional as F- Tensor paralllel
- 更细粒度的模型并行,细到weight matrix(tensor)粒度
- 通信报销较大
- 可拓展性强
- 数学上:矩阵分块
分块矩阵
Spliting a two-layer MLP across two devices:
将矩阵分块,每一块可以放在不同的显卡当中计算完的结果再进行加和
import numpy as npX = np.random.randn(100,200)
A = np.random.randn(200,300)
B = np.random.randn(300,400)
def split_columnwise(A,num_splits):
	return np.split(A,num_splits,axis=1)
def split_rowwise(A,num_splits):
	return np.split(A,num_splits,axis=0)
def normal_forward_pass(X,A,B,f):
Y = f(np.dot(X,A))
Z = np.dot(Y,B)
return Zdef tensor_parallel_forward_pass(X,A,B,f):
A1,A2 = split_columnwise(A,2)
B1,B2 = split_rowwise(B,2)
Y1 = f(np.dot(X,A1))
Y2 = f(np.dot(X,A2))
Z1 = np.dot(Y1,B1)
Z2 = np.dot(Y2,B2)
Z=Z1+Z2
return ZZ_normal = normal_forward_pass(X,A,B,np.tanh)
Z_tensor = tensor_parallel_forward_pass(X,A,B,np.tanh)Z_tensor.shape#判断二者是否近似相等
np.allclose(Z_normal,Z_tensor)FFN
- h->4h
- 4h->h
ffn of bert
from transformers import AutoModelimport os
os.environ["http_proxy"]="http://127.0.0.1:7890"
os.environ["https_proxy"]="https://127.0.0.1:7890"bert = AutoModel.from_pretained('bert-base-uncased')#h-->4h
bert.encoder.layer[0].intermediatebert.encoder.layer[0].outputffn cases
input = torch.randn(size=[1,5,10],dtype=torch.float32)embedding_dim = input.size(2)
embedding_dimdense_h_to_4h = nn.Linear(embedding_dim,embedding_dim*4,bias=False)
#(1,5,10)->(1,5,40)
output1=dense_h_to_4h(input)
output1.shapedesne_4h_to_h = nn.Linear(embedding_dim*4,embedding_dim,bias=False)
output2=dense_4h_to_h(output)
output2.shapen_device = 2
half_4h = embedding_dim*4//n_devicesdense_h_to_4h_parallel = nn.Linear(embedding_dim,half_4h,bias=False)
dense_h_to_4h_parallel.weight.data = dense_h_to_4h.weight[:half_4h,:]
first_h_to_4h = dense_h_to_4h_parallel(input)
first_h_to_4h.shapedense_h_to_4h_parallel = nn.Linear(embedding_dim,half_4h,bias=False)
dense_h_to_4h_parallel.weight.data = dense_h_to_4h.weight[half_4h:,:]
second_h_to_4h = dense_h_to_4h_parallel(input)
second_h_to_4h.shapedense_4h_to_h_parallel = nn.Linear(half_4h,embedding_dim,bias=False)
dense_4h_to_h_parallel.weight.data = dense_4h_to_h.weight[:,half_4h:]
fisrt_4h_to_h = dense_4h_to_h_parallel(input)
first_4h_to_hdense_4h_to_h_parallel = nn.Linear(half_4h,embedding_dim,bias=False)
dense_4h_to_h_parallel.weight.data = dense_4h_to_h.weight[:,half_4h:]
second_4h_to_h = dense_4h_to_h_parallel(input)
second_4h_to_hfirst_4h_to_h+second_4h_to_houtput2first_4h_to_h+second_4h_to_h == output2Attention
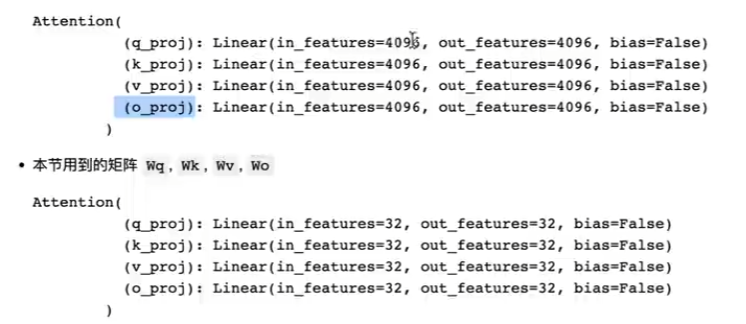
bert.encoder.layer[0].attention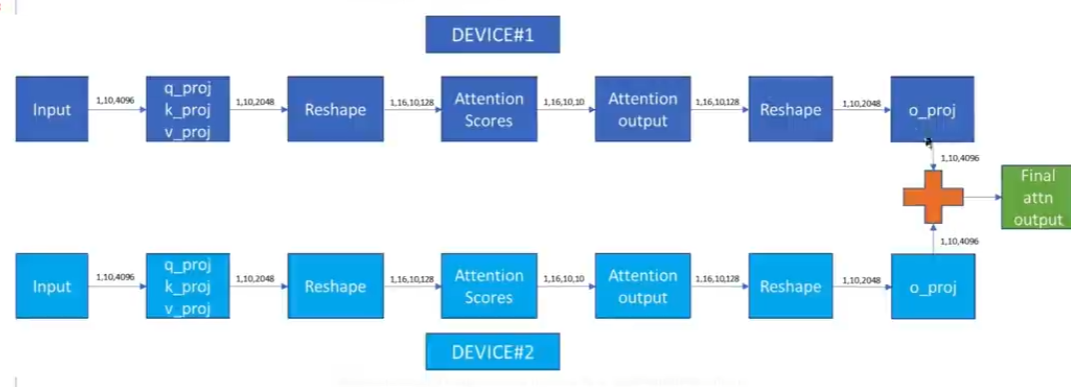
input = torch.randn(size=(1,5,32),dtype=torch.float32)不经过任何模型并行的结果
bsz,seq_len,hidden_size = input.size()
hidden_size
num_heads = 4
head_dim = head_size // num_heads
head_dimWq = nn.Linear(hidden_size,num_heads*head_dim,bias=False)
Wk = nn.Linear(hidden_size,num_heads*head_dim,bias=False)
Wv = nn.Linear(hidden_size,num_heads*head_dim,bias=False)
Wo = nn.Linear(num_heads*head_dim,hidden_size,bias=False)q = Wq(input)
k = Wk(input)
v = Wv(input)
q = q.view(bsz,sqe_len,num_heads,head_dim).transpose(1,2)
k = k.view(bsz,seq_len,num_heads,head_dim).transpose(1,2)
v = v.view(bsz,seq_len,num_heads,head_dim).transpose(1,2)
v.shapeattn_weights = F.softmax(attn_wieghts,dim=1)
attn_output = torch.matmul(atten_weights,v)
attn_output.shapeattn_output = attn_output.transpose(1,2).contiguous()
attn_output = attn_output.reshape(bsz,seq_len,num_head*head_dim)
attn_output.shapeattn_output_non_tp = Wo(attn_output)
attn_output_non_tp.shapeattn_output_non_tptp of Attention
n_devices = 2
num_heads = num_heads//n_devicesWq.weight.shapeWq_blocks = Wq.weight.split(num_heads*head_dim,dim=0)
print(q_blocks[0].shape)
print(q_blocks[1].shape)Wk_blocks = Wk.weight.split(num_heads*head_dim,dim=0)
Wv_blocks = Wv.weight.split(num_heads*head_dim,dim=0)Wo_blocks = Wo.weight.split(num_heads*head_dim,dim=1)
print(Wo_block[0].shape)
print(Wo_block[1].shape)q1 = F.linear(input,Wq_blocks[0])
k1 = F.linear(input,Wk_blocks[0])
v1 = F.linear(input,Wv_blocks[0])q1 = q1.view(bsz,seq_len,num_heads,head_dim).transpose(1,2)
k1 = k1.view(bsz,seq_len,num_heads,head_dim).transpose(1,2)
v1 = v1.view(bsz,seq_len,num_heads,head_dim).transpose(1,2)attn_weights = torch.matmul(q1,k1.transpose(2,3))
attn_weights = F.softmax(attn_weights,dim=1)
attn_output1 = torch.matmul(attn_weights,v1)
attn_output1 = attn_output1.transpose(1,2).contiguous()
attn_output1.shapeattn_output1 = attn_output1.reshape(bsz,seq_len,num_heads*head_dim)attn_output1.shapeWo_blocks[0].shapeattn_output1 = F.linear(attn_output1,Wo_blocks[0])
attn_output1.shapeq2 = F.linear(input,Wq_blocks[1])
k2 = F.linear(input,Wk_blocks[1])
v2 = F.linear(input,Wv_blocks[1])
q2 = q2.view(bsz,seq_len,num_heads,head_dim).transpose(1,2)
k2 = k2.view(bsz,seq_len,num_heads,head_dim).transpose(1,2)
v2 = v2.view(bsz,seq_len,num_heads,head_dim).transpose(1,2)
attn_weights = torch.matmul(q2,k2.transpose(2,3))
attn_weights = F.softmax(attn_weights,dim=1)
attn_output2 = torch.matmul(attn_weights,v2)attn_output2.shapeattn_output2 = attn_output2.reshape(bsz,seq_len,num_heads*head_dim)attn_output = attn_output1+attn_output2attn_output.shape